Retail Sales ETL Pipeline- Snowflake to BigQuery
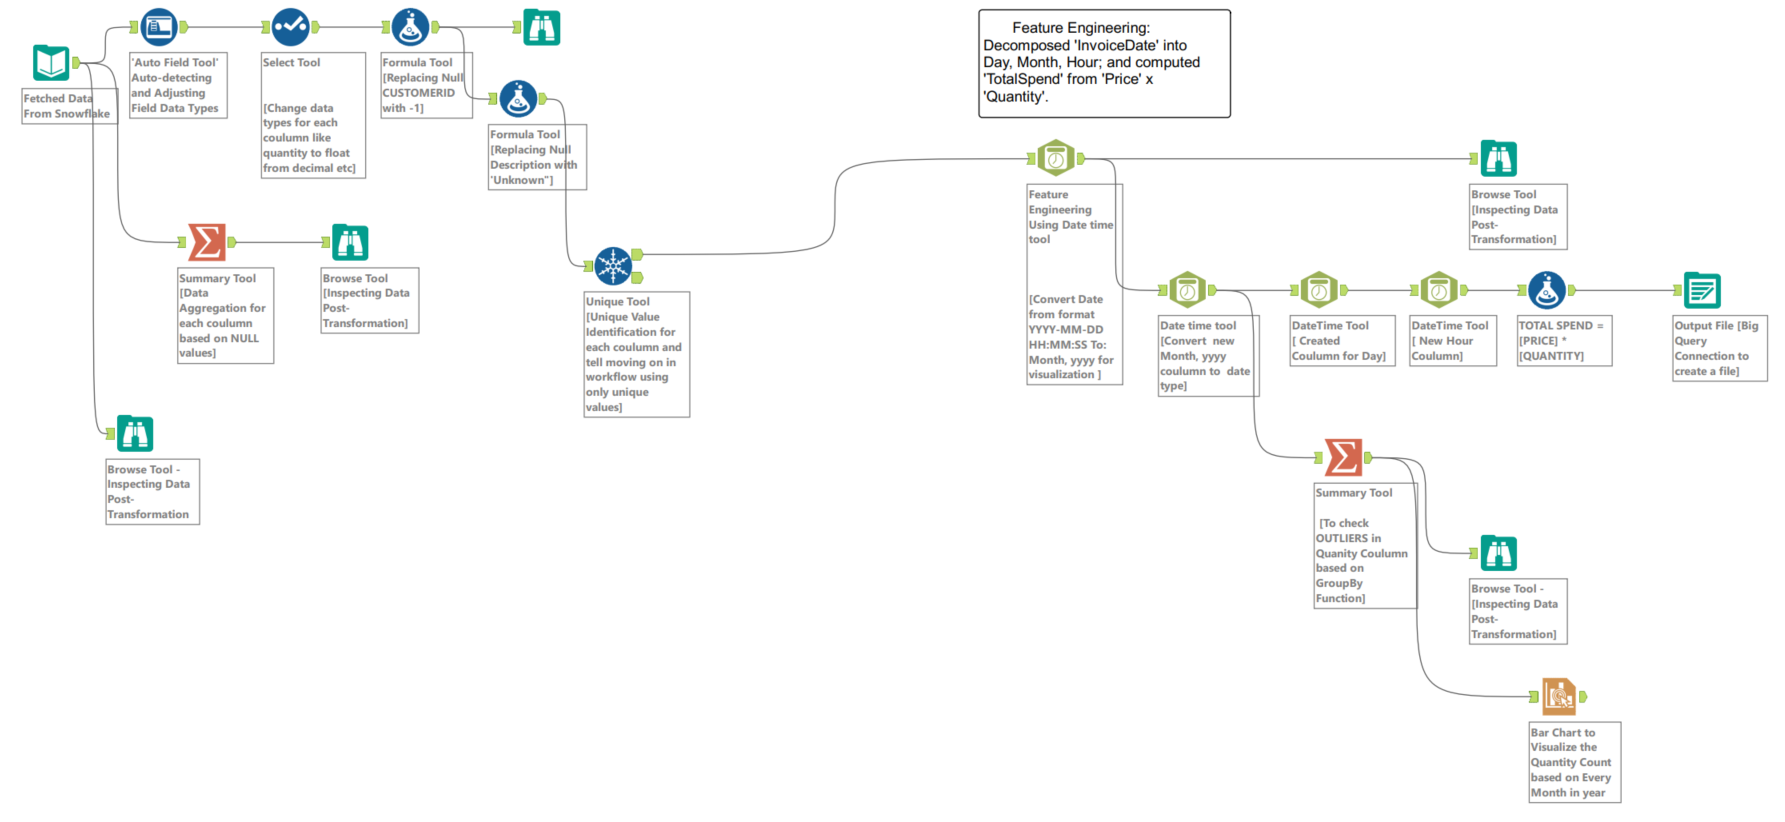
🌟 Highlights: Retail Sales Data Transformation and Visualization
Skills: Snowflake · Alteryx · BigQuery · Tableau · ODBC · SQL · Windows Task Scheduler · Data Warehousing · ETL
📦 Data Extraction:
• Utilized UC Irvine Retail Sales Data with 1,067,372 records. Dataset Link: here.
• Excel to CSV conversion.
• Established warehouse, database, schema, and table in Snowflake for raw data.
• Verified data integration on Snowflake with SQL Queries: Link for Code
🔄 Transformation:
• Snowflake to Alteryx connection via ODBC.
• Alteryx Workflow: Null value handling (customerID set to -1, description set to "unknown").
• 80% threshold fuzzy match for description discrepancies.
• Deduplication based on unique values.
🔧 Feature Engineering:
• New columns for Day, Hour, Month for visualizations.
• New columns for total spend and total return {Price*Quantity}.
Realtime Socket Streaming Using Apache Spark
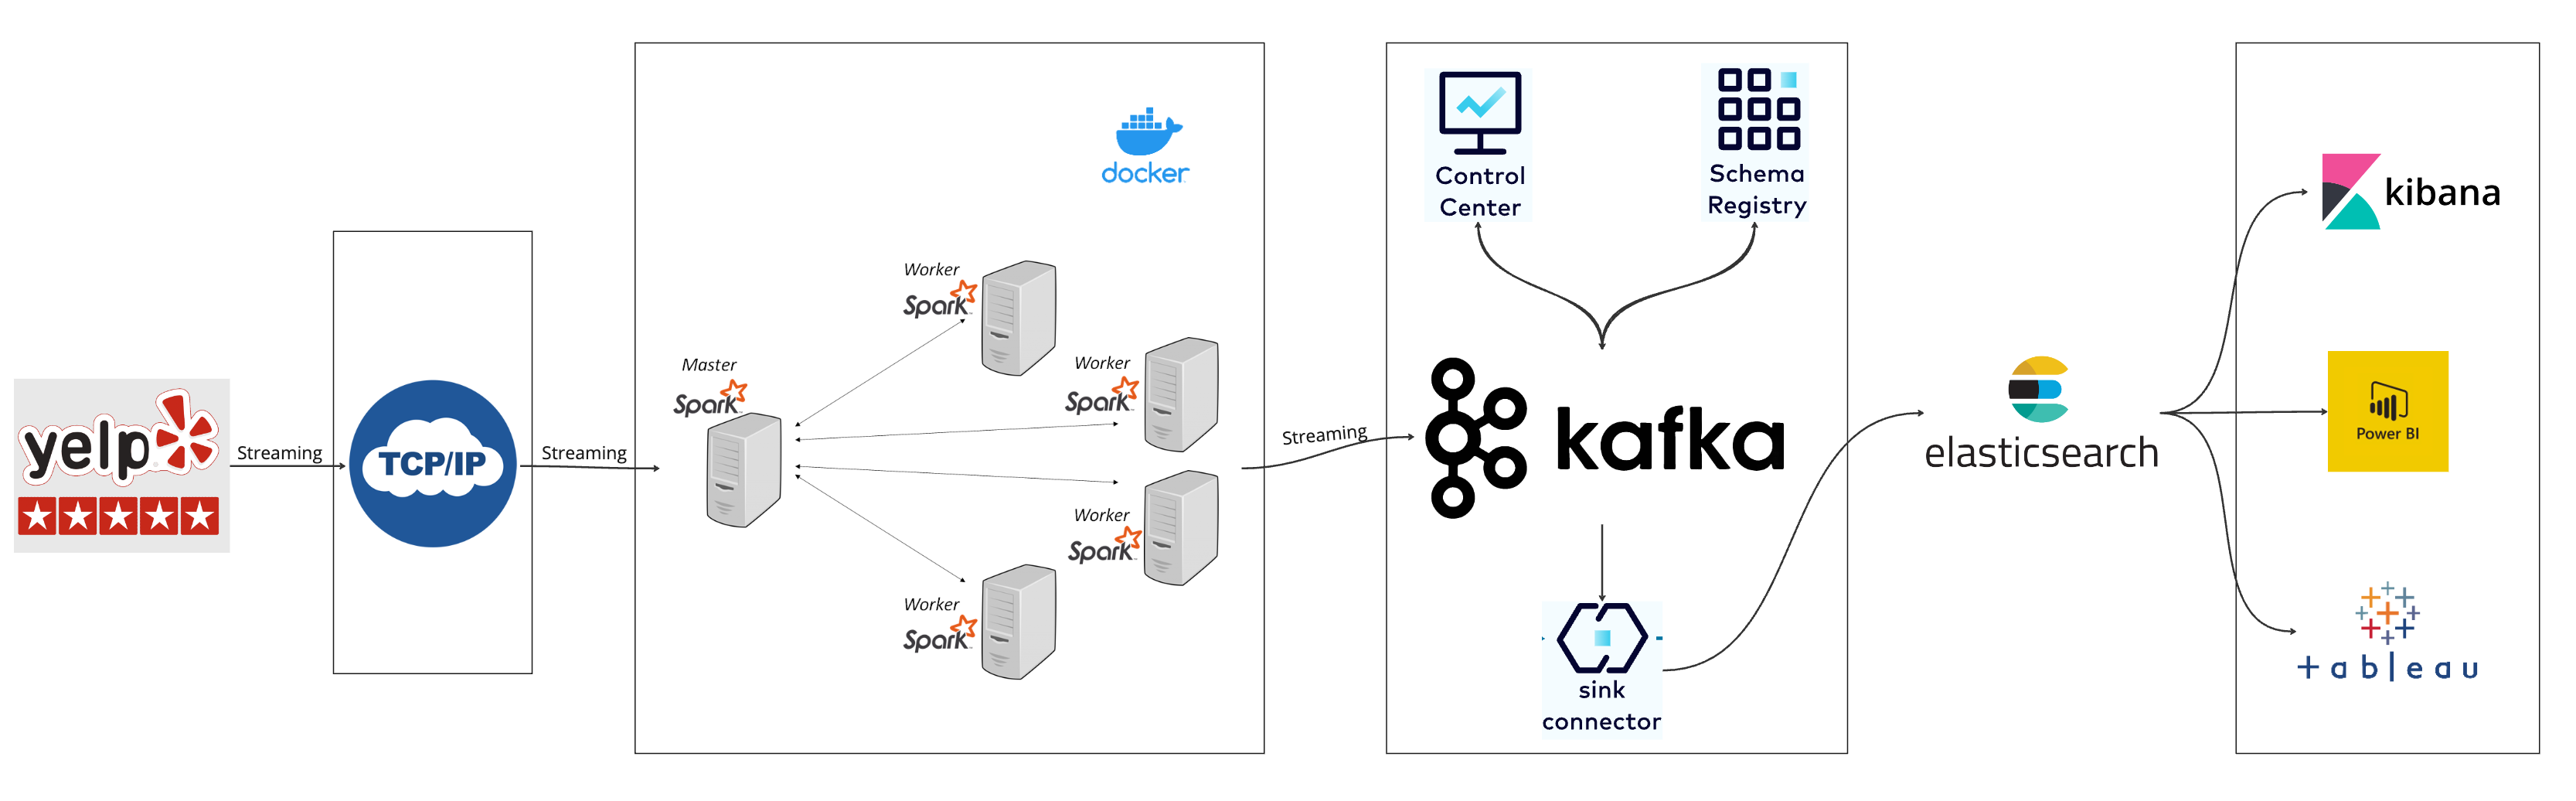
Tools and Technologies Used:
TCP/IP Socket, Apache Spark, OpenAI Large Language Model LLM, Kafka, Elastic Search, Kibana , Docker
Data:
- Yelp Dataset 7 million records (~10 GB)
Overview:
- Real-time Sentiment Analysis of 7 million records by streaming on TCP/IP socket connection. Using Apache Spark for sentiment analysis with LLM, streaming to Kafka, indexing to Elasticsearch, and visualizing in Kibana.
- Data Streaming (streaming-socket.py)
- Socket Setup: Created a socket to stream Yelp reviews (host: 0.0.0.0, port: 9999).
- Throttled Streaming: 87-second delay between data chunks (2 records) for controlled streaming.
- Limitations: Due to cost considerations and OpenAI API limits, streaming is currently limited to 1000 records per day.
- Error Handling: Implemented handling for disconnections and errors like BrokenPipeError, ConnectionResetError.
AWS-Based ETL Pipeline for Reddit Data
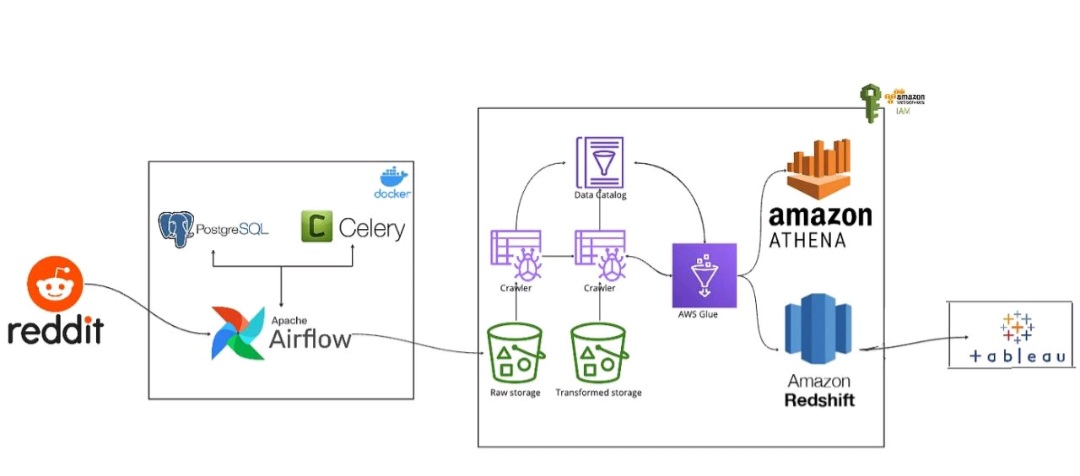
🔍 Project Overview: Crafted an ETL pipeline for Reddit data, specifically targeting the subreddit "MachineLearning".
Tools & Platforms Used: Apache Airflow, Python, AWS S3, AWS Redshift, AWS Athena, AWS Glue, Tableau, PostgreSQL, Redis, Docker, PRAW, Pandas, Spark.
📦 Data Extraction:
• Connected to Reddit using PRAW with credentials stored securely.
• Extracted top posts from the "MachineLearning" subreddit using filters for the time period and post limit of 100.
🔄 Data Transformation:
• Employed Pandas and NumPy to handle data cleaning tasks like converting timestamps and handling boolean data types.
• Created a new 'tag_type' field from post titles.
🔧 AWS S3 Integration:
• Configured AWS S3 bucket for structured 'raw' data storage.
• Uploaded transformed data to S3 using S3FS.
Azure-Based ETL Pipeline for OTT Platform Data
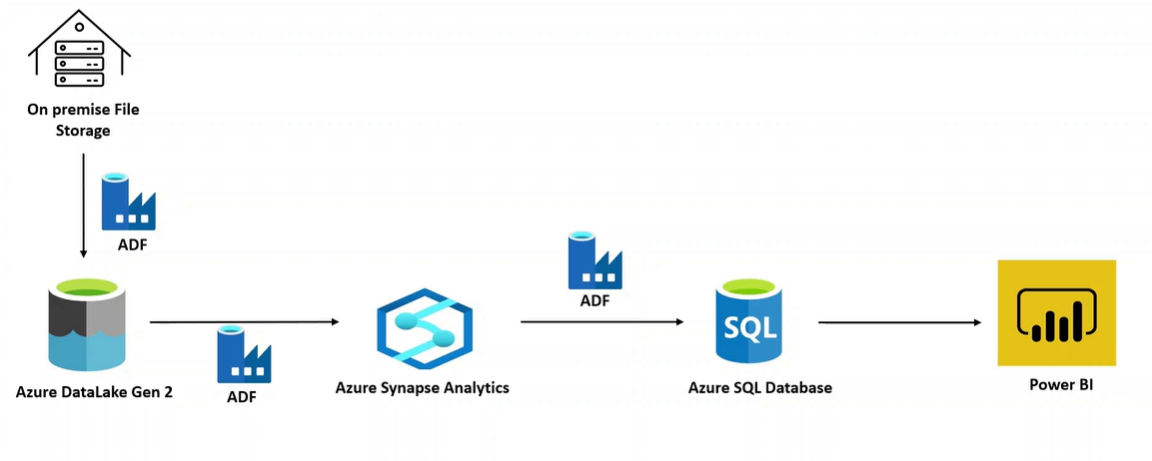
🔍 Project Overview: Developed an ETL pipeline for OTT platform data, focusing on data from popular platforms like Netflix, Disney+, and Prime.
Tools & Platforms Used: Azure, Azure Datalake Storage Gen2, Azure Data Factory, Azure Synapse Analytics, Azure SQL Database, Azure Logic App, PowerBI, Azure DevOps Git, Microsoft SSMS, Email Notifications.
📦 Data Extraction:
• Used a dummy dataset of OTT platforms from Kaggle.
• Set up a budget in Azure to receive email alerts when expenses cross a threshold.
• Initialized the Azure infrastructure with a resource group, Azure Datalake Storage Gen2, Azure Data Factory, Azure Synapse Analytics, and an Azure SQL Database.
🔄 Azure Data Factory Ingestion:
• Used a self-hosted runtime to transfer data from on-premise to Azure Data Lake Gen2.
• Implemented Azure Key Vault for data security and linked services for data transfer between on-premise and cloud.
• Developed pipelines to ingest data into a 'raw' folder in Azure Data Lake Gen2.
• Implemented two incremental data loading strategies:
a. Based on the 'last modified' timestamp of files.
b. Utilizing date details from filenames like "2022-04-12 110513.455313" for specific day data ingestion.
Amazon Data Scrapping
Skills: Beautiful Soup · Simple Mail Transfer Protocol (SMTP)
🔍 Developed a Python web scraping script for Amazon shirt price monitoring, leveraging BeautifulSoup and requests libraries.
📧 Implemented an automated email system, notifying my Gmail for price drops below set threshold.
⚙️ Utilized SMTP protocol & smtplib library, ensuring secure connection to Gmail's SMTP server for direct email delivery.
🗂️ Integrated CSV handling, recording shirt details & dates for insightful historical price tracking.
💡 Demonstrated expertise in data manipulation using datetime & csv libraries for accurate data management.
💪 Overcame challenges in scraping data and handling Gmail's security measures.
Twitter Data Scraper Using API
Skills: NLTK · twitterscraper · spaCy · pandas
🐦 Fetched and Analyzed Twitter Data of User 'realDonaldTrump' using twitterscraper.
🔍 Conducted Text Preprocessing: Tokenization, Stemming, Stop Word Removal, and Punctuation Handling using nltk.
📊 Performed Exploratory Data Analysis (EDA) to Reveal Most Frequent Words in Tweets.
📈 Visualized Top 20 Words with Bar Plot using seaborn Library.
📝 Utilized spacy for Named Entity Recognition (NER) to Extract Organizations and People Mentioned.
🏢 Presented Top 20 Organizations Mentioned with Bar Plot using seaborn.
👥 Highlighted Top 20 People Mentioned with Bar Plot using seaborn.
📊 Created Data Visualizations to Showcase Key Insights from Twitter Data.
As of April 2023, free access to the API for academic or research purposes is unavailable. Third-party tools like TwitterScrapper can't retrieve tweets either. For those wanting to use Tweepy's official Twitter scraping API, there's a charge of $100 for searching tweets. As a result, the "try yourself" feature in my portfolio is not functioning.
Automating Crypto Website API Pull Using Python
Skills: API Integration · JSON Handling · Pandas · Data Visualization · Seaborn · Error Handling
🔄 Developed a Python script to automate the collection of cryptocurrency data from CoinMarketCap's API.
📊 Normalized JSON data into a Pandas dataframe, enabling efficient data analysis and transformation.
📈 Visualized cryptocurrency price percentage changes over different time frames using Seaborn.
🕐 Added a timestamp column to track data retrieval time, aiding in trend analysis.
🔍 Conducted focused analysis on specific cryptocurrencies, exemplified by Bitcoin price trends over time.
💡 Demonstrated expertise in data manipulation, transformation, and visualization to generate actionable insights.
💪 Tackled challenges like API call errors, ensuring seamless data retrieval and analysis.